

🚀 FREE DOWNLOAD: Karpathy’s Complete AI Knowledge Compiler System
Hey, Before you dive in, download the full ready-to-run kit I built so you can skip the manual setup entirely.
I packaged everything into one free zip file:
Pre-built schemas + page templates (entity, pattern, synthesis, etc.)
Perfect folder structure for raw sources + wiki pages
Automation scripts for one-click ingestion
Weekly maintenance workflows
All 6 tested prompts + extras
Real example wiki pages (competitive intel, objections, etc.)
Step-by-step instructions for Claude Code / Claude Cowork / Obsidian
Drop it in and you’ll have your own self-updating compiled LLM knowledge base running in minutes instead of hours.
⬇️ Get the Full Compiled Knowledge Base System
Are you AI-enabled or AI-native?
This may look like another ‘AI-slop’ question... but it’s not... if you read and understand how it is actually impacting.
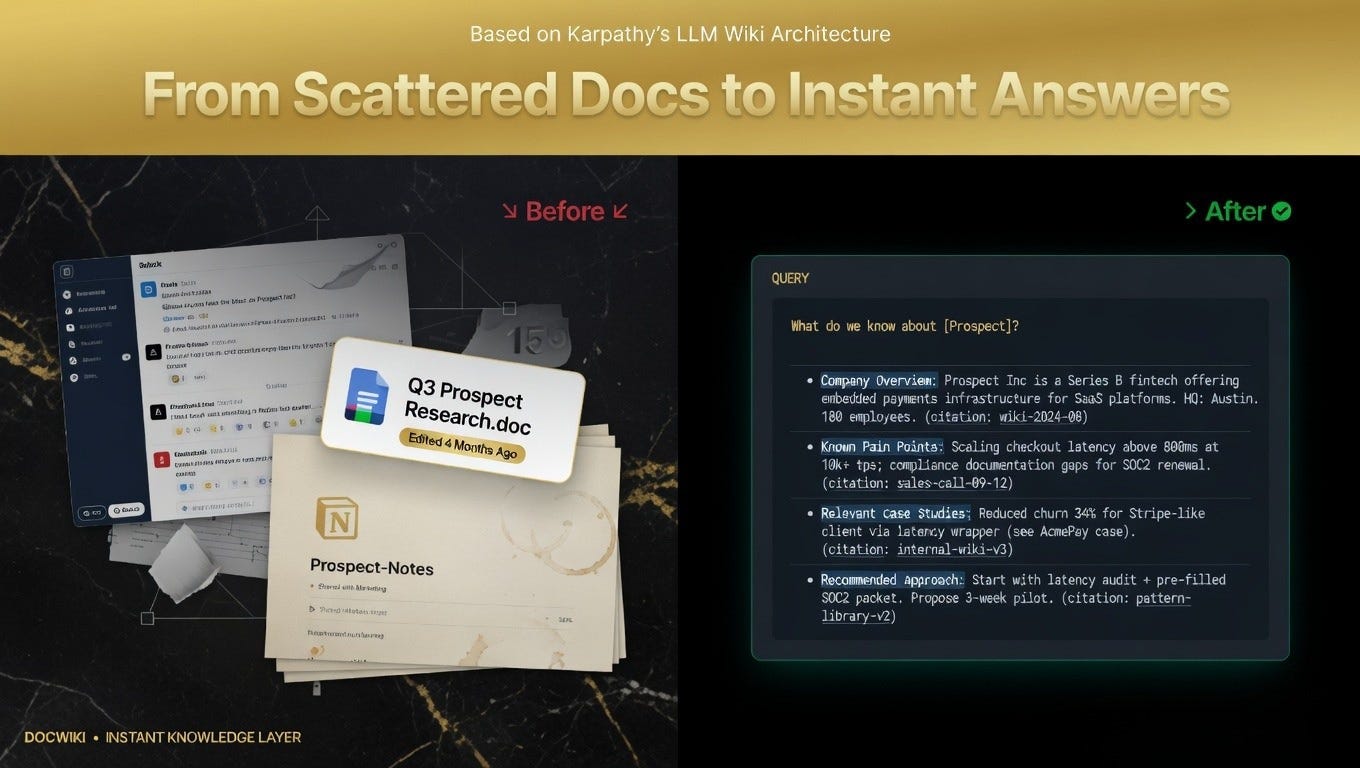
If i explain, AI-native means your AI agents are all working from the same compiled, cross-referenced knowledge base.
When you ask Claude about a competitor, it’s not searching the internet. It’s querying your wiki, which was built from your call transcripts, your G2 reviews, your win/loss notes.
When a new deal closes, Claude Code automatically updates the relevant pages.
When your ops agent runs a weekly summary, it’s pulling from the same docs your sales agent used yesterday.
The difference is the underlying context
Here’s what changes when you become AI-native...
Before a sales call: Your rep asks Cowork about the prospect’s competitor. It returns a compiled page: current positioning, known pricing, objections that came up in the last six deals where this competitor was mentioned, and the synthesis page flagging that they moved upmarket three months ago. That page was built from 40 internal and external sources.
When a new hire joins: They don’t schedule 12 knowledge-transfer meetings. They ask your AI agent questions. The agent queries the compiled wiki and returns institutional memory.
When a market shift happens: Three things changed in the same quarter. A competitor removed their pricing page. A second competitor got acquired. Pricing objections in your pipeline doubled. No single person noticed the pattern. Your wiki compiled a synthesis page connecting all three and flagged it for review.
None of this happens when you’re AI-enabled. It only happens when the AI is working from unified, compiled context i.e. a knowledge base that all your agents share, that updates itself, and that gets more useful every week.
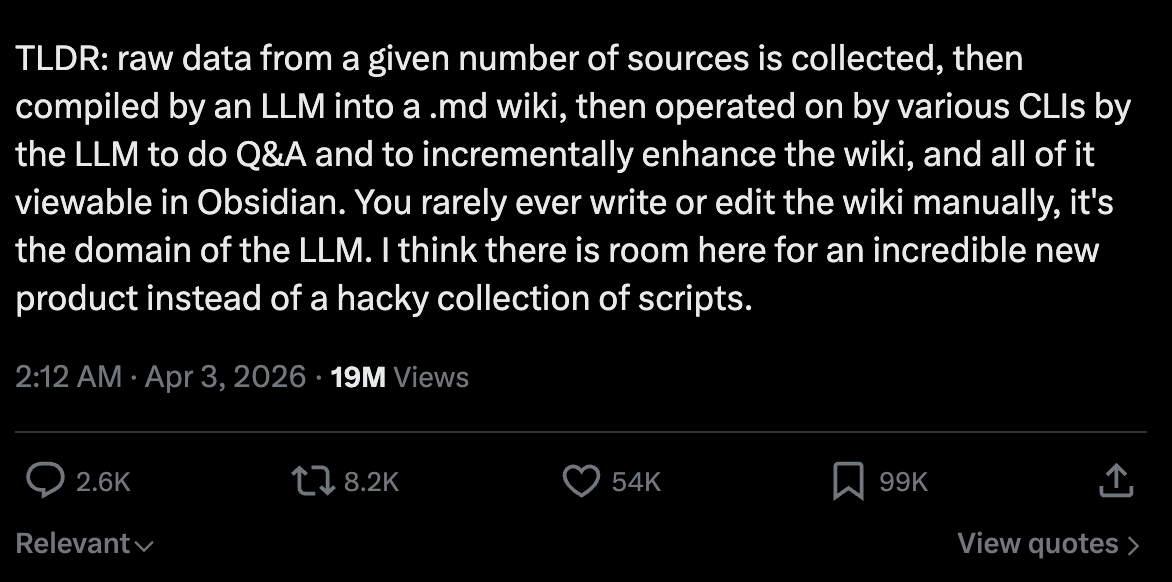
This unified knowledge base architecture is exactly Andrej Karpathy published in his latest X post. 19 million impressions on that post.
In this edition:
Why Karpathy’s post went viral and what it actually means
Who should build this (4 team profiles + before/after)
The 3-layer architecture, explained
Examples: what compiled wiki pages look like
How to build a free version in 90 minutes
The 6-month plan from test to team deployment
6 copy-paste prompts (tested across 120 scenarios)
FAQ + three ways to start building
Why 16 Million People Stopped Scrolling
Karpathy built the AI powering Tesla’s self-driving system. He was a founding member of OpenAI. Stanford PhD in deep learning. He’s spent over a decade figuring out how machines learn from messy, unstructured data.
When someone with that background says the way most people use AI for knowledge management is fundamentally broken, it means there is some serious understanding problem.
Folks shared it because he solved a problem that everyone was having.
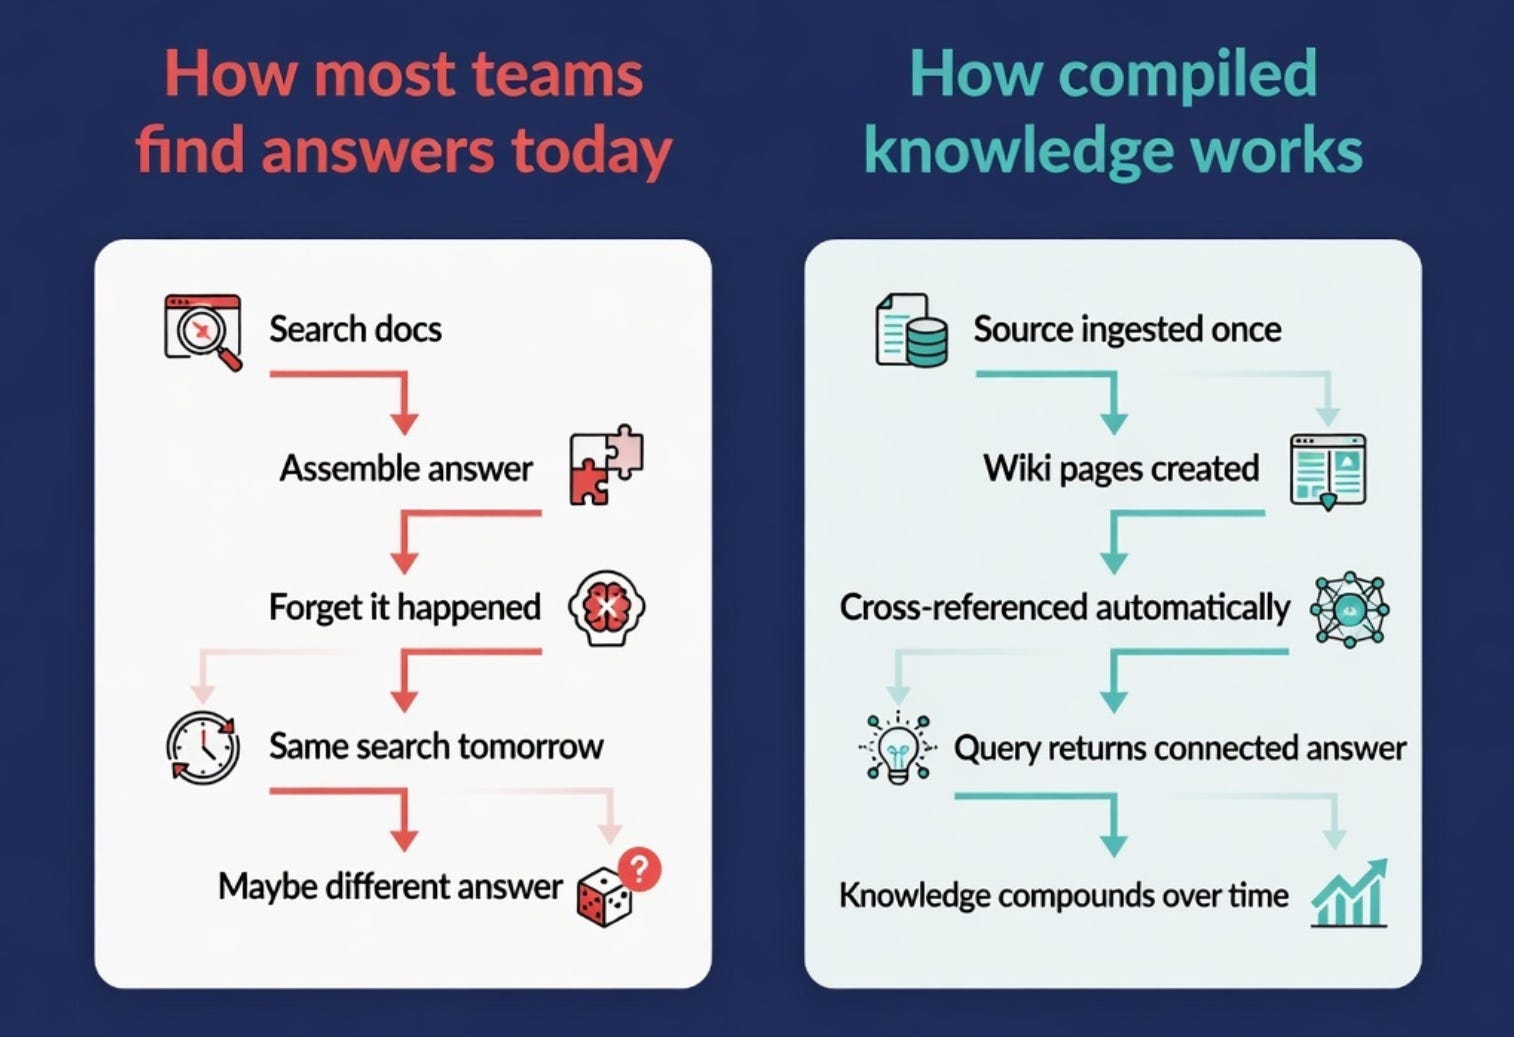
Every time you ask an AI about your documents, it starts from zero. It searches through your files, assembles an answer on the spot, and forgets it happened. Ask the same question tomorrow and it runs the same search again. The answer might even differ because it pulled from a different set of documents.
Google’s NotebookLM does this. Your CRM’s AI search does this. Uploading files to ChatGPT does this. Every “AI knowledge” tool on the market right now is a smarter search engine. It’s not a knowledge system.
This approach is called RAG (retrieval-augmented generation): the AI searches your raw documents from scratch on every query.
Karpathy’s Insight: Compile Once, Query Forever
Karpathy’s insight was a different architecture entirely. Instead of re-deriving answers from raw documents every time, have the AI compile a structured knowledge base.
Wiki pages that link to each other.
Entity profiles that cross-reference source materials.
When new information arrives, the AI doesn’t start over. It reads the new source, updates existing pages, flags contradictions, and adds to the overall base.
His own system grew to roughly 100 articles and 400,000 words of compiled knowledge. He didn’t write any of it directly. He fed sources, asked questions, and the system built and maintained itself.
His idea is to not “use AI to search your docs.” That’s been around for years. Use AI to maintain a knowledge base that compounds over time.
And it applies directly to how you / your team handles the knowledge it already has.
I’ve spent the last few months helping GTM teams build versions of this. The pattern is the same every time: the knowledge exists, the retrieval is broken, and the first compiled wiki page makes the problem obvious.
Loved so far?
Who Should Build an AI Knowledge Base (And What Changes When You Do)
This is for anyone running a team where the same knowledge is used across projects, agents and GPTs everytime.
Four groups in particular will get the most out of what follows.
GTM and sales leaders.
Your reps re-research the same competitors every quarter. A new AE joins and spends six weeks figuring out what your top closer already knows.
After you build this: a new rep looks up any competitor before a call and gets the full picture in two minutes. Every deal teaches the next rep. Objection responses come from actual call transcripts. Your competitive intelligence updates automatically from internal and external sources.
Consulting and professional services.
Your best insights and discussion notes are in email threads, decks, and the heads of senior people.
When someone leaves, five to fifteen years of nuanced understanding also goes away. Your team builds new frameworks which are already there...but no-one has time to find across sources.
After you build this: a consultant working a new supply chain engagement can pull up what worked in the last eight supply chain projects and get specific frameworks, client feedback, and outcome data. Institutional knowledge becomes an asset that grows with every project.
Product and engineering leaders.
Your team’s decisions scatter across Confluence, Notion, Slack, and individual memories. You’re about to make an architecture choice that contradicts original reasoning....but knowone knows what was it.
After you build this: any engineer can search “why did we choose Postgres over DynamoDB for the payments service” and get the original decision record with the alternatives considered.
Solo founders and operators.
You wear every hat. Your edge is 50+ client engagements worth of pattern recognition, but it’s all in your head. You can’t surface every relevant case during a live conversation. When you hire your first team member, there’s no system for transferring what you know.
After you build this: you search “B2B SaaS moving from per-seat to usage-based pricing” and get every relevant case you’ve ever worked, what happened, what failed, and what you tried. Your personal IP becomes searchable, connected, and something you can actually hand off.
What you’ll walk away with from this newsletter specifically:
The architecture.
A zero-cost way to test it in 90 minutes.
A six-month plan from first test to full team deployment.
And six copy-paste prompts that handle strategy, planning, and implementation, tested across 20 industries and company stages.
A two-person startup can build a basic version in 90 minutes. A 50-person team can scale it into a full organizational knowledge layer. The architecture is the same either way. The depth grows with you.
Save this. You’ll come back to it.
If you want to skip the manual setup entirely:
I built the full compiled knowledge base system as a downloadable zip-file with schemas, folder structure, automation scripts, maintenance workflows. It works one-click in Claude Code or Claude Cowork. Details at the end of this newsletter.
How the LLM Wiki Architecture Works: Three Layers Explained
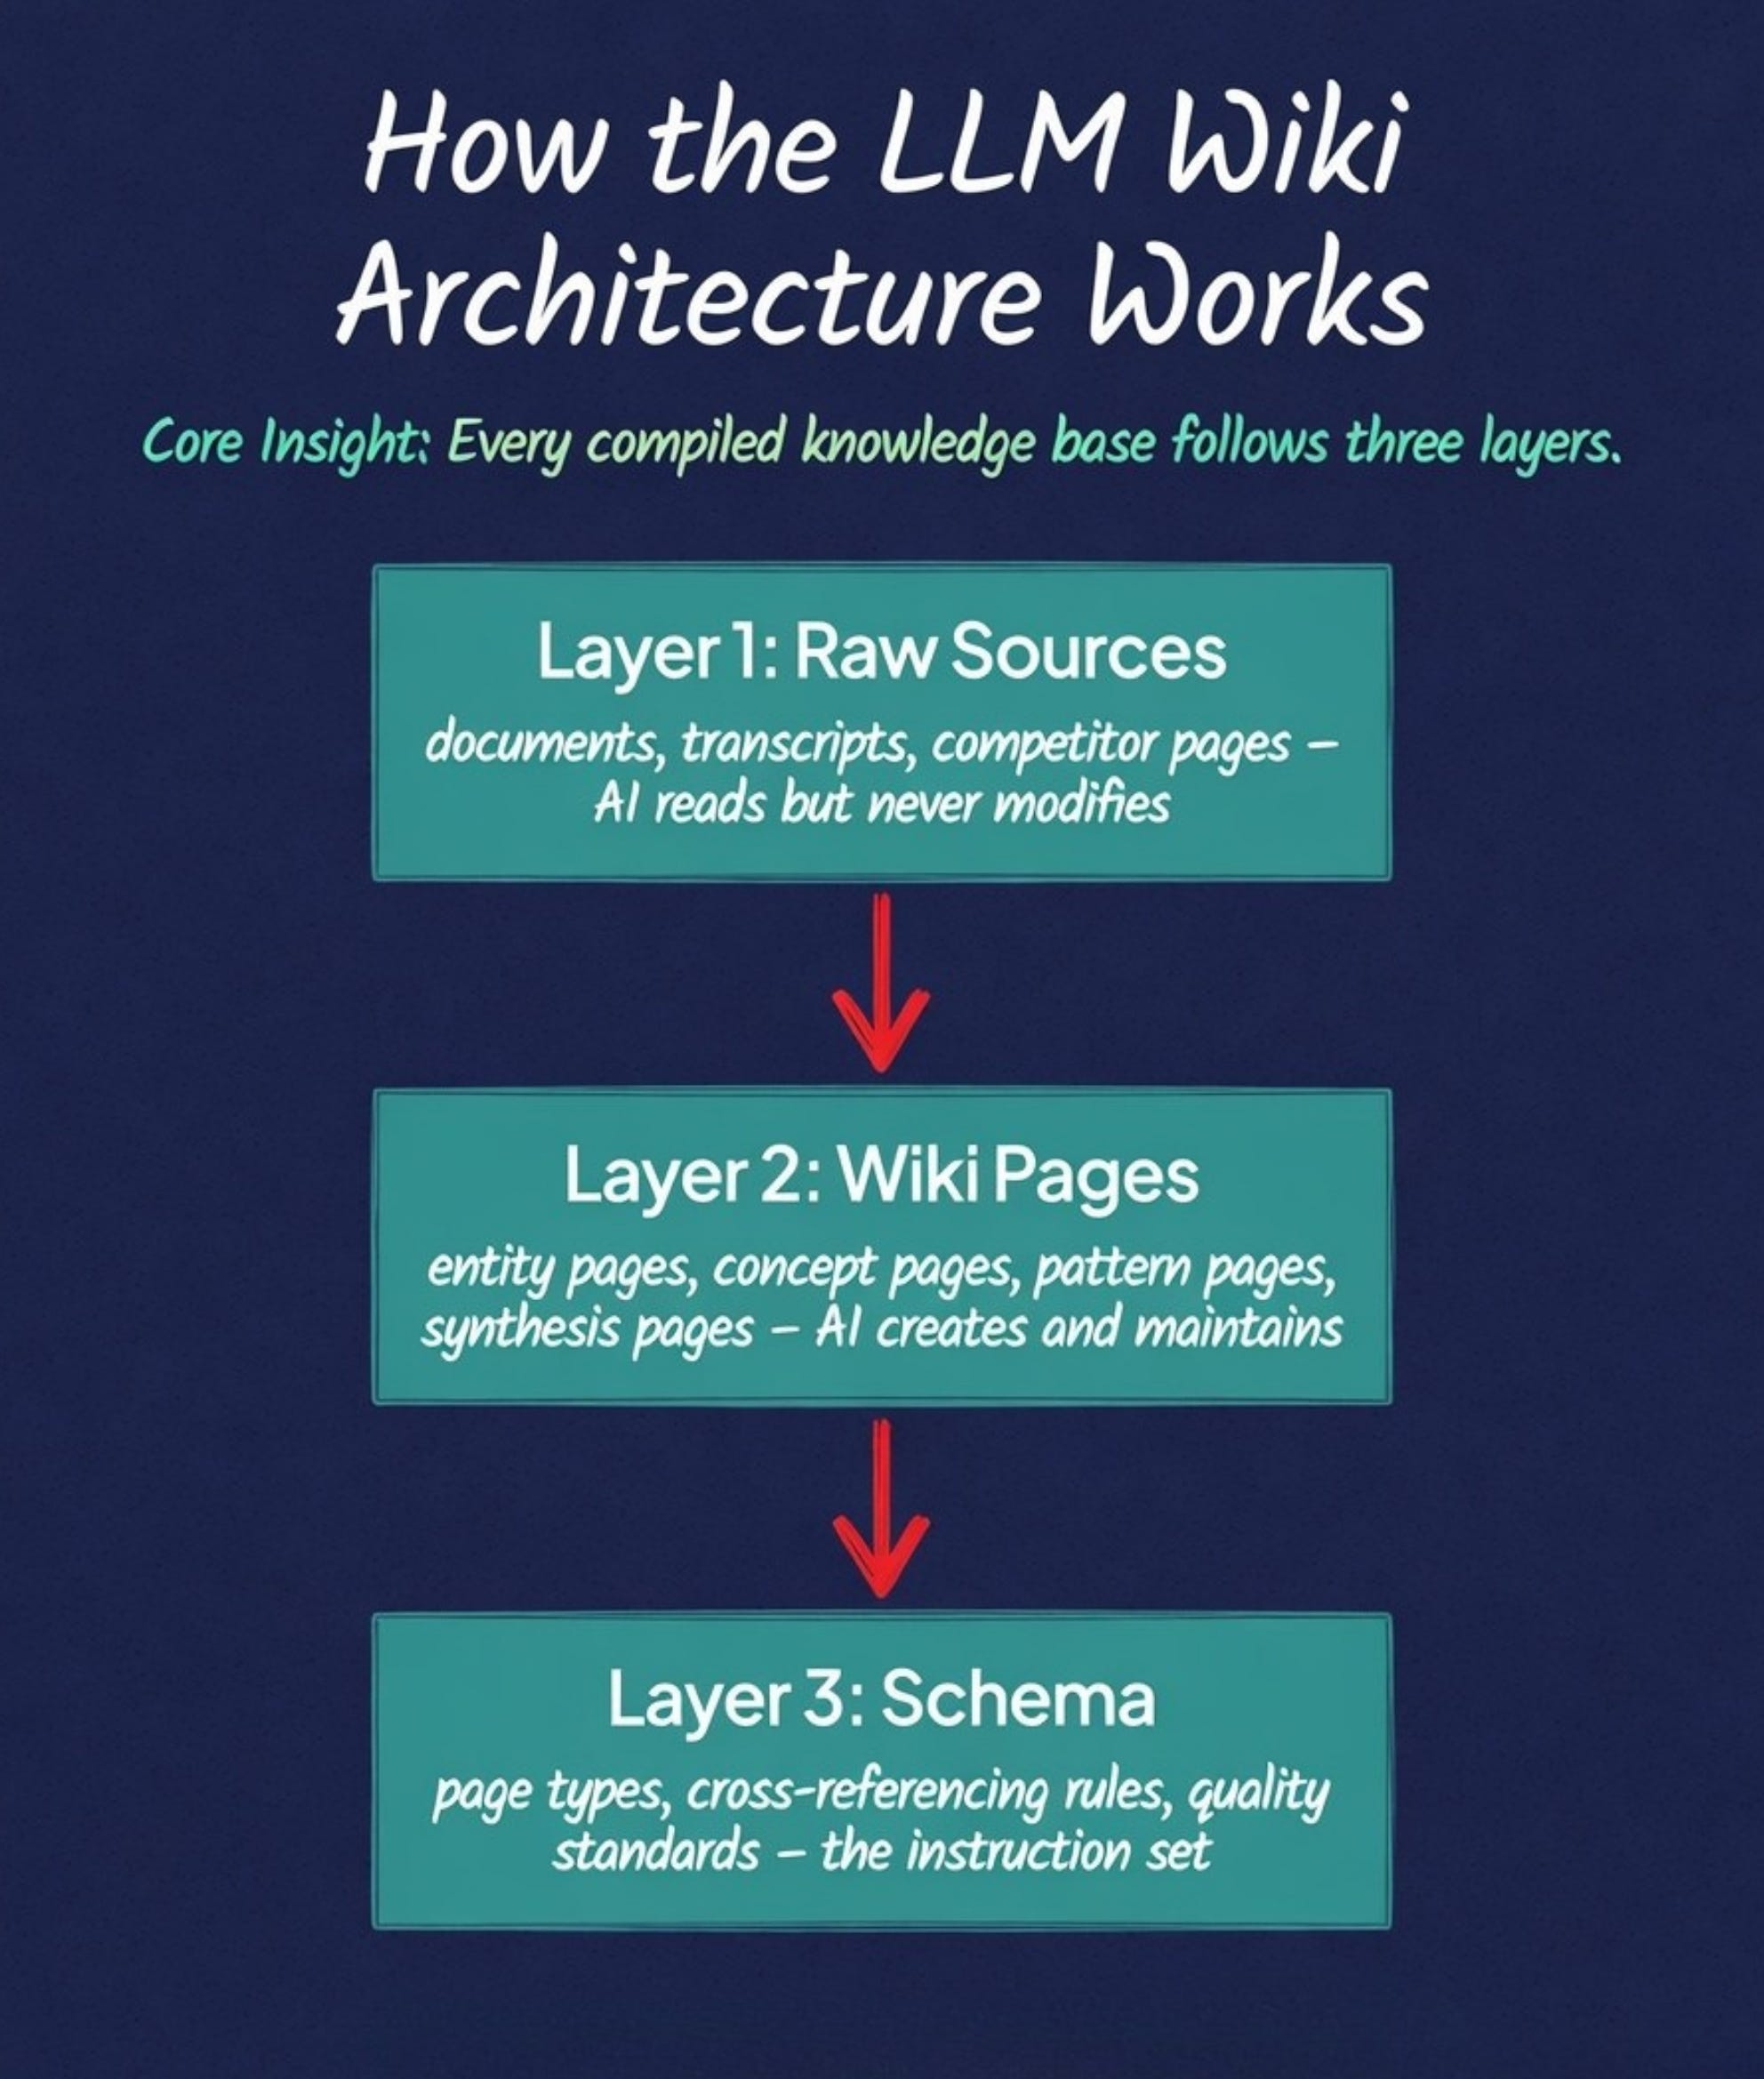
It has three layers. Every implementation follows this same structure, whether you’re using paid tools or building it free.
Layer 1: Raw Sources
A folder of documents the AI reads but never modifies.
Call transcripts.
Competitor blog posts.
Pricing pages.
Research articles.
G2 reviews.
Meeting notes.
Industry reports.
Whatever your team currently has across Slack, Google Drive, Notion, and email threads.
One rule: raw sources are immutable. The AI reads them but never changes them. This is your source of truth, untouched.
Layer 2: Wiki Pages
This is where the it starts working. The AI reads your raw sources and creates structured, interlinked wiki pages. These are not summaries. These are connected knowledge artifacts that reference each other.
The page types that work for business knowledge:
Entity pages for people, companies, products, and tools. A competitor entity page pulls from every raw source that mentions them: call transcripts, pricing pages, G2 reviews, blog posts. One page. Always current.
Concept pages for frameworks, mental models, and strategic ideas. Your best thinking about pricing strategy, ICP targeting, or content approach. Compiled from multiple conversations and documents, not trapped in a single deck nobody opens anymore.
Source summary pages for every raw document ingested. The AI reads a 45-minute call transcript and creates a one-page summary with key takeaways, action items, and links to relevant entity and concept pages.
Pattern pages that track recurring themes. Which objections come up most in sales calls. Which content formats perform best. What messaging connects with which segments. The AI spots these patterns because it’s reading across all your sources, not just the ones you happened to open this week.
Synthesis pages that connect dots across multiple page types. A competitor’s pricing shift, combined with an increase in pricing objections on sales calls, combined with their blog post announcing a new enterprise tier, adds up to one finding: they’re moving upmarket and your mid-market positioning needs to respond. No single person would have connected those threads without manually reading every source. The compiled wiki surfaces it automatically.
Layer 3: The Schema
The schema is the instruction set that tells the AI how to compile.
It defines what page types to create, how to structure metadata at the top of each page, how to cross-reference pages, when to flag contradictions, and what quality standards to maintain.
Most teams reach this point and ask the same question: how is this different from what they’re already using?
What you’re probably using How it works The catch Google Drive / Notion search Searches file names and text within documents Finds files, not answers. Knowledge stays siloed in individual docs. No cross-referencing. RAG (ChatGPT file upload, NotebookLM) AI searches raw documents on every query Re-derives the answer from scratch every time. Same question can produce different answers. No persistent knowledge. Traditional wiki (Confluence, Notion) Humans write and maintain pages manually Goes stale within weeks because nobody updates it. No automatic cross-referencing. Compiled knowledge base (LLM wiki) AI reads sources once, creates interlinked pages, updates over time Requires initial setup and a schema. Once running, it compounds without manual effort.
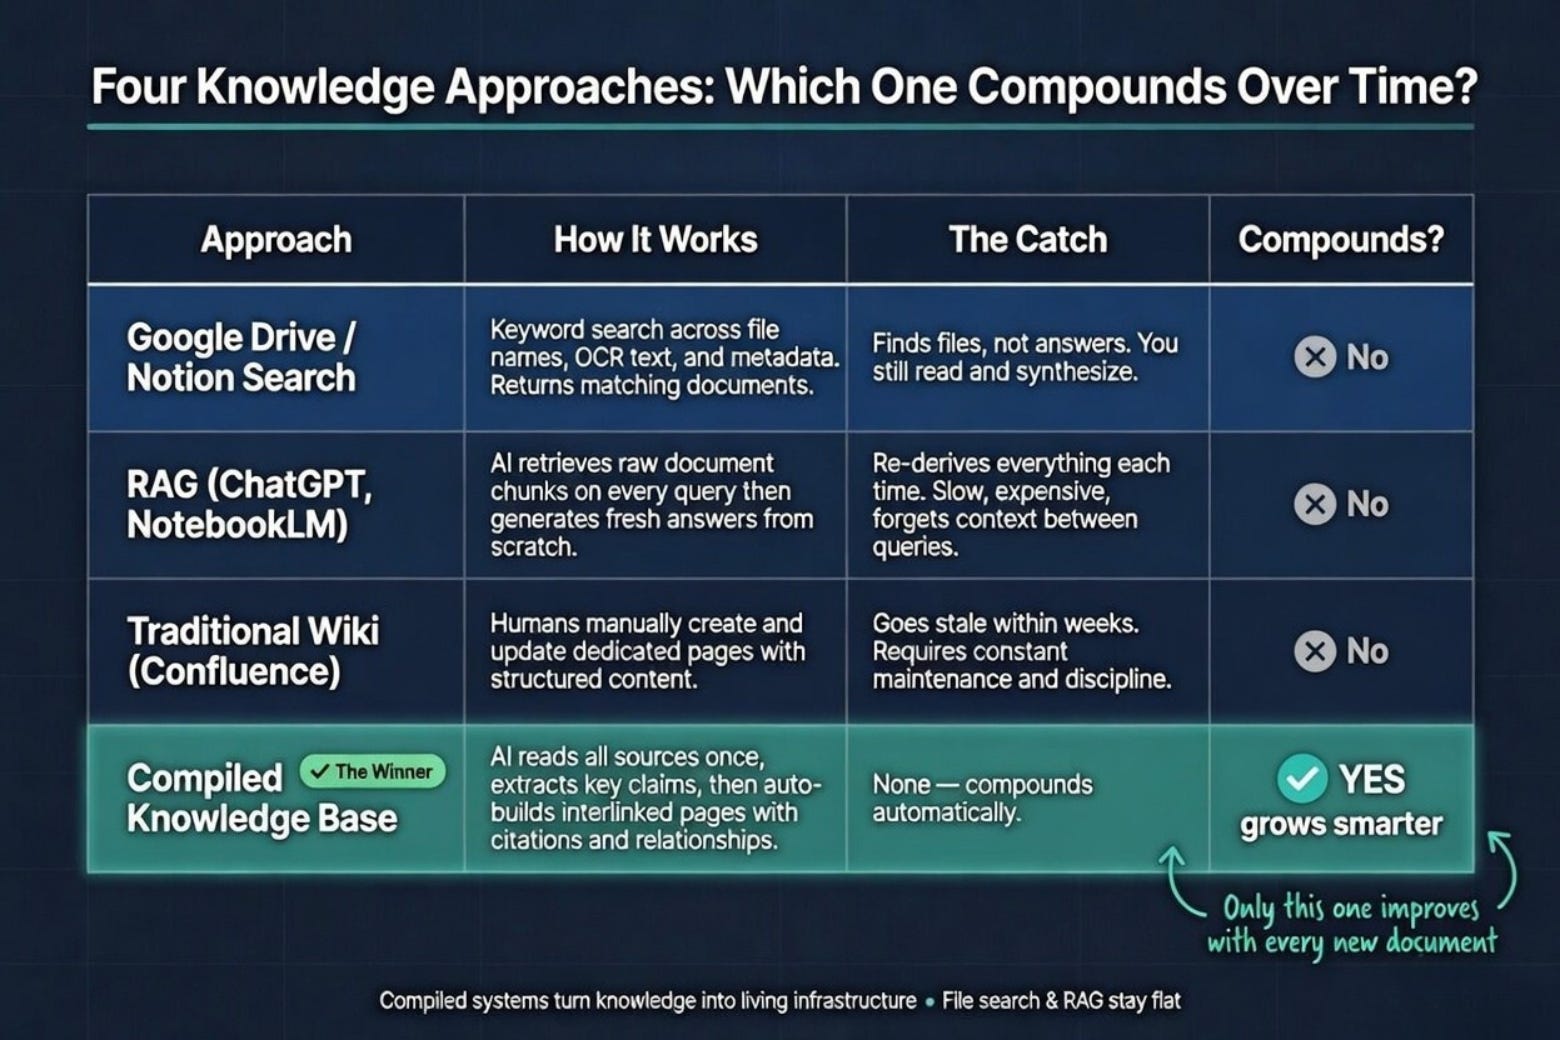
The pattern is the same for everything in the first three rows. They all make you do the synthesis every time you need an answer. The compiled knowledge base does it once and keeps the result.
The Tools
Obsidian holds the knowledge base. It’s a markdown editor that lives on your local machine, no cloud required. Every wiki page is a plain text file. Its real strength is bidirectional linking.
When a competitor entity page links to an objection response page, Obsidian shows that connection from both sides. You can see every page that references a competitor, every concept tied to a deal pattern. The graph view shows you how the entire knowledge base fits together.
Claude Code, or any LLM with file access, is the compiler. It reads raw sources, creates wiki pages following your schema rules, updates existing pages when new sources arrive, and flags contradictions. You give it a command like “ingest everything in raw/competitive/” and it reads each source, creates or updates relevant entity pages, logs the operation, and updates the master index.
Claude Cowork gives you a conversational interface on top of the same system. Mount your knowledge base folder, ask a question, and it searches compiled wiki pages for answers. The difference from regular AI chat: it’s searching cross-referenced, pre-compiled knowledge instead of re-deriving from raw documents.
Claude Code builds and maintains the wiki.
Obsidian stores and visualizes it.
Cowork lets you query it conversationally.
You can automate maintenance so the wiki stays current without you doing anything except dropping new sources into the raw folder.
If you want to start free: Logseq instead of Obsidian, ChatGPT free tier as the compiler, manual markdown editing. The architecture is the same. The automation is what you add later.
What a Compiled AI Knowledge Base Looks Like in Practice
Here’s what a competitive intelligence wiki looks like after ingesting 10 sources: a mix of competitor website pages, G2 reviews, and sales call transcripts.
A competitor entity page:
---
page_type: entity
entity_type: company
name: Gong
status: active
confidence: high
authority_source: official
last_updated: 2025-03-15
sources: [gong-pricing-page-2025, g2-gong-reviews-q1, call-transcript-acme-discovery]
---

# Gong

## Overview
Revenue intelligence platform. Primary competitor in the call recording
and conversation analytics space. Series E, valued at $7.2B (2021).
Publicly signaling a move toward full revenue platform positioning
(not just call recording).

## Positioning
Currently messaging as "Revenue AI Platform" rather than conversation
intelligence. Shift happened in late 2024. Their homepage no longer
leads with call recording. Leads with "AI that tells you what's
happening in your pipeline."

## Pricing
Enterprise-only pricing. No self-serve. Minimum contract ~$15K/year
based on prospect feedback from [[call-transcript-acme-discovery]].
Per-seat model with platform fee. Exact numbers vary by deal size.

**Changelog:**
- 2025-03: Confirmed $15K minimum from Acme discovery call
- 2024-11: Removed public pricing page entirely

## Strengths (from G2 reviews)
- Call recording quality consistently rated 4.5+
- CRM integration (Salesforce) rated strongest in category
- See [[pattern-gong-strengths-from-reviews]] for full breakdown

## Weaknesses (from G2 reviews and sales calls)
- Implementation time: multiple G2 reviews cite 6-8 weeks
- "Analytics are powerful but overwhelming for reps who just want
  the basics" — recurring theme across 4 reviews
- See [[pattern-gong-weaknesses-from-reviews]]

## Objections mentioning Gong
- [[pattern-pricing-objections-q1]] — 3 of 8 pricing objections
  in Q1 referenced Gong's pricing as their benchmark
- [[call-transcript-betacorp-negotiation]] — prospect explicitly
  compared our per-seat cost to Gong's

## Related pages
- [[synthesis-competitor-pricing-shifts-q1]]
- [[entity-chorus]] (secondary competitor, acquired by ZoomInfo)
- [[concept-revenue-intelligence-category]]
One page, three sources: a website, G2 reviews, and a sales call transcript. It has a changelog tracking when pricing information was confirmed. It links to pattern pages, other entity pages, and synthesis pages.
If you add a new source next month that mentions Gong, this page gets updated automatically. Nobody has to remember to do it.
A pattern page:
---
page_type: pattern
name: Pricing Objections Q1 2025
confidence: high
authority_source: internal-expert
last_updated: 2025-03-20
sources: [call-transcript-acme-discovery, call-transcript-betacorp-negotiation,
  call-transcript-gamma-demo, call-transcript-delta-closing, qbr-q1-sales-review]
---

# Pricing Objections Q1 2025

## Pattern summary
8 deals in Q1 had pricing as a primary objection. Of those, 5 were
mid-market (50-200 employees) and 3 were enterprise. The mid-market
objections clustered around absolute price ("we don't have budget for
this category"). The enterprise objections clustered around comparative
price ("Gong quoted us less" or "we already pay for Salesforce Einstein").

## What's working
- Anchoring on time saved per rep per week (see [[concept-roi-calculator]])
  converted 3 of the 5 mid-market objections
- Enterprise objections responded better to integration story:
  "you're already paying for 4 tools that do pieces of this"

## What's not working
- Straight discounting closed 0 of 8 pricing objections
- Feature comparison decks are not landing — 2 prospects said
  "we already know the features, that's not the issue"

## Trend
Pricing objections increased from 4 in Q4 2024 to 8 in Q1 2025.
Correlates with [[entity-gong]] removing their public pricing page
(creating uncertainty) and [[entity-chorus]] being acquired by
ZoomInfo (removing a lower-price alternative from market).

## Connected pages
- [[synthesis-competitor-pricing-shifts-q1]]
- [[entity-gong]]
- [[entity-chorus]]
- [[concept-roi-calculator]]
This page didn’t exist in any single source. No one document said pricing objections doubled quarter over quarter and here’s why.
The AI read across five separate call transcripts and the Q1 sales review, spotted the pattern, and compiled it into one page. A new rep joining in Q2 reads this and immediately understands the pricing landscape without sitting through eight call recordings.
A synthesis page (the one that connects dots nobody connected manually):
---
page_type: synthesis
name: Competitor Pricing Shifts Q1 2025
confidence: medium
authority_source: internal-expert
last_updated: 2025-03-22
sources: [gong-pricing-page-2025, zoominfo-chorus-acquisition-announcement,
  pattern-pricing-objections-q1, qbr-q1-sales-review]
---

# Competitor Pricing Shifts Q1 2025

## Synthesis
Three things happened in the same quarter:
1. [[entity-gong]] removed their public pricing page and moved to
   enterprise-only sales (confirmed via website monitoring)
2. [[entity-chorus]] was acquired by ZoomInfo, effectively removing
   the most common lower-price alternative from the market
3. Pricing objections in our pipeline doubled from 4 to 8
   (see [[pattern-pricing-objections-q1]])

## What this means
The competitive pricing floor just rose. Gong is moving upmarket.
Chorus is gone as a standalone option. Prospects who used to have
a $10K alternative now have fewer options under $15K.

## Recommended response
Our mid-market positioning ($8K-$12K range) is now the value play
in this category by default. This wasn't true 6 months ago when
Chorus existed. Update the mid-market pitch to lead with:
"The last affordable option in revenue intelligence."

## Open questions
- Will ZoomInfo bundle Chorus into their existing contracts? If yes,
  the "affordable alternative" disappears entirely from new deals.
- Should we raise mid-market pricing given reduced competition?

## Connected pages
- [[entity-gong]]
- [[entity-chorus]]
- [[pattern-pricing-objections-q1]]
- [[concept-competitive-positioning]]
That synthesis page is the one nobody would have written manually. It connects a competitor’s website change, an acquisition announcement, and a spike in sales objections into one finding: the competitive pricing floor shifted, and your positioning needs to respond.
That insight was sitting in four different people’s heads and never getting combined. The wiki does the combining.
These three pages came from 10 raw sources. After 50 sources, you have a full competitive intelligence system that any team member can query and that updates itself every time you drop a new source into the folder.
How to Build a Free AI Knowledge Base in 90 Minutes
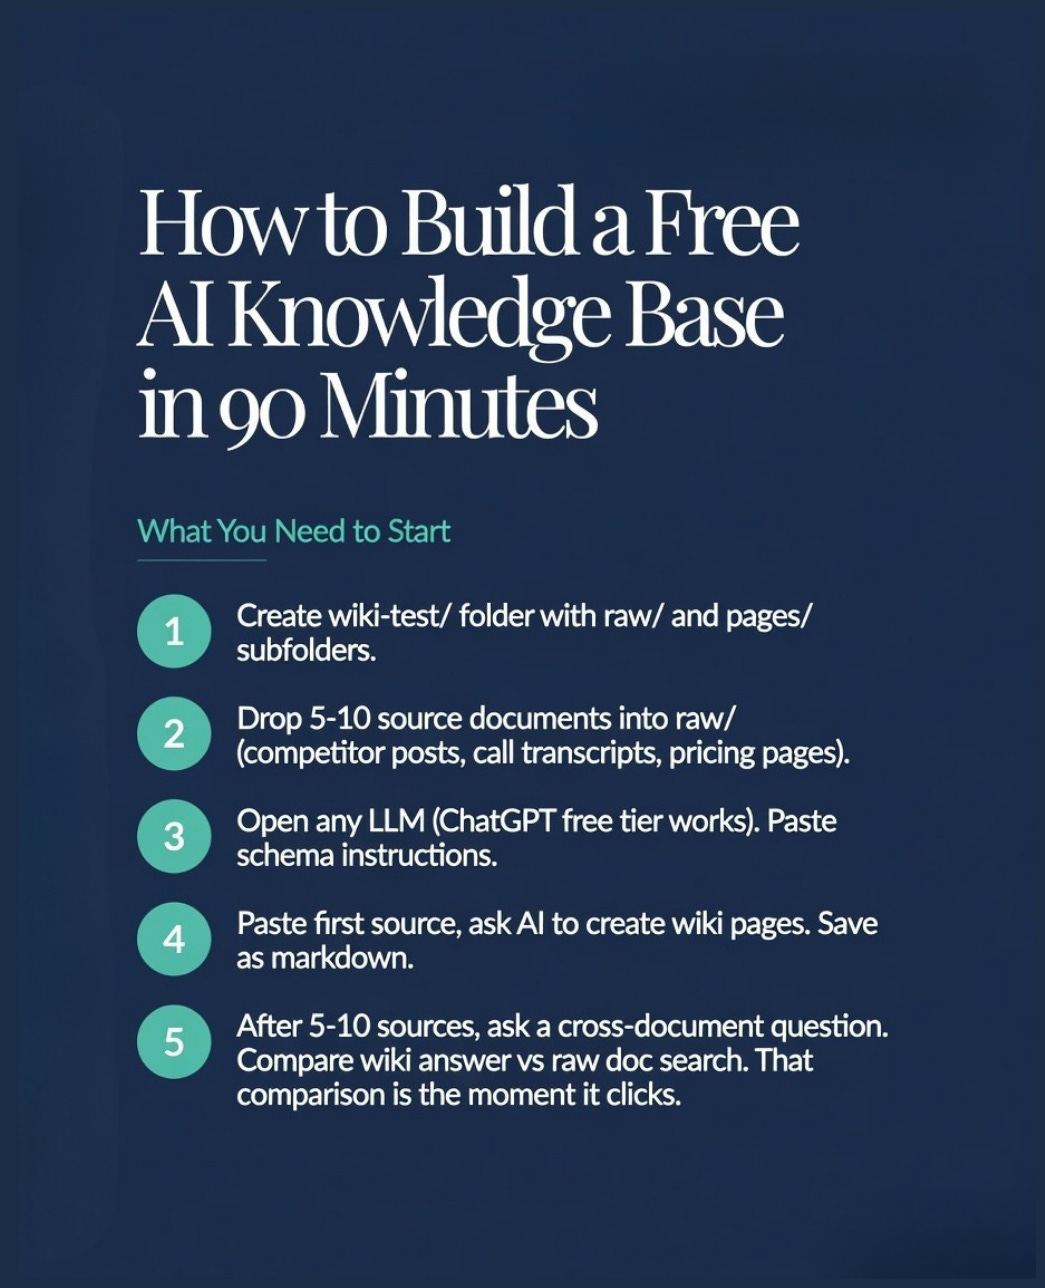
You don’t need paid tools to test this. The architecture is tool-agnostic. Everything below is free.
For the knowledge base: Logseq. Free, open-source, works almost identically to Obsidian. Local-first. Bidirectional backlinks. Markdown files. If you want something even more bare-bones, Joplin or VS Code with a markdown preview extension both work.
For the LLM compiler: ChatGPT free tier is fine for a basic test. You won’t get file-system access, so you’ll copy-paste source content directly into the chat and manually save the wiki pages it generates. If you want it local and private, run Ollama on your machine with Llama 3 or Mistral. Free. Offline. No API costs.
The workflow:
Create a folder called
wiki-test/with two subfolders:raw/andpages/. Drop five to ten source documents intoraw/. Competitor blog posts, call transcript excerpts, pricing pages converted to text. Keep it focused on one topic. Competitive intelligence is the easiest place to start.Open your LLM. Paste the schema instructions from Section 5 below. Paste your first source document and ask it to create wiki pages following the schema. Save the output as markdown files in
pages/. Add cross-references manually using[[Page Name]]links. Repeat for each source.After five to ten sources, ask the LLM a question that requires connecting information across multiple documents. Then compare that answer against what you’d get from searching the raw documents directly.
That comparison is the moment it clicks. The wiki answer will be faster and more connected because the knowledge is already compiled and cross-referenced.
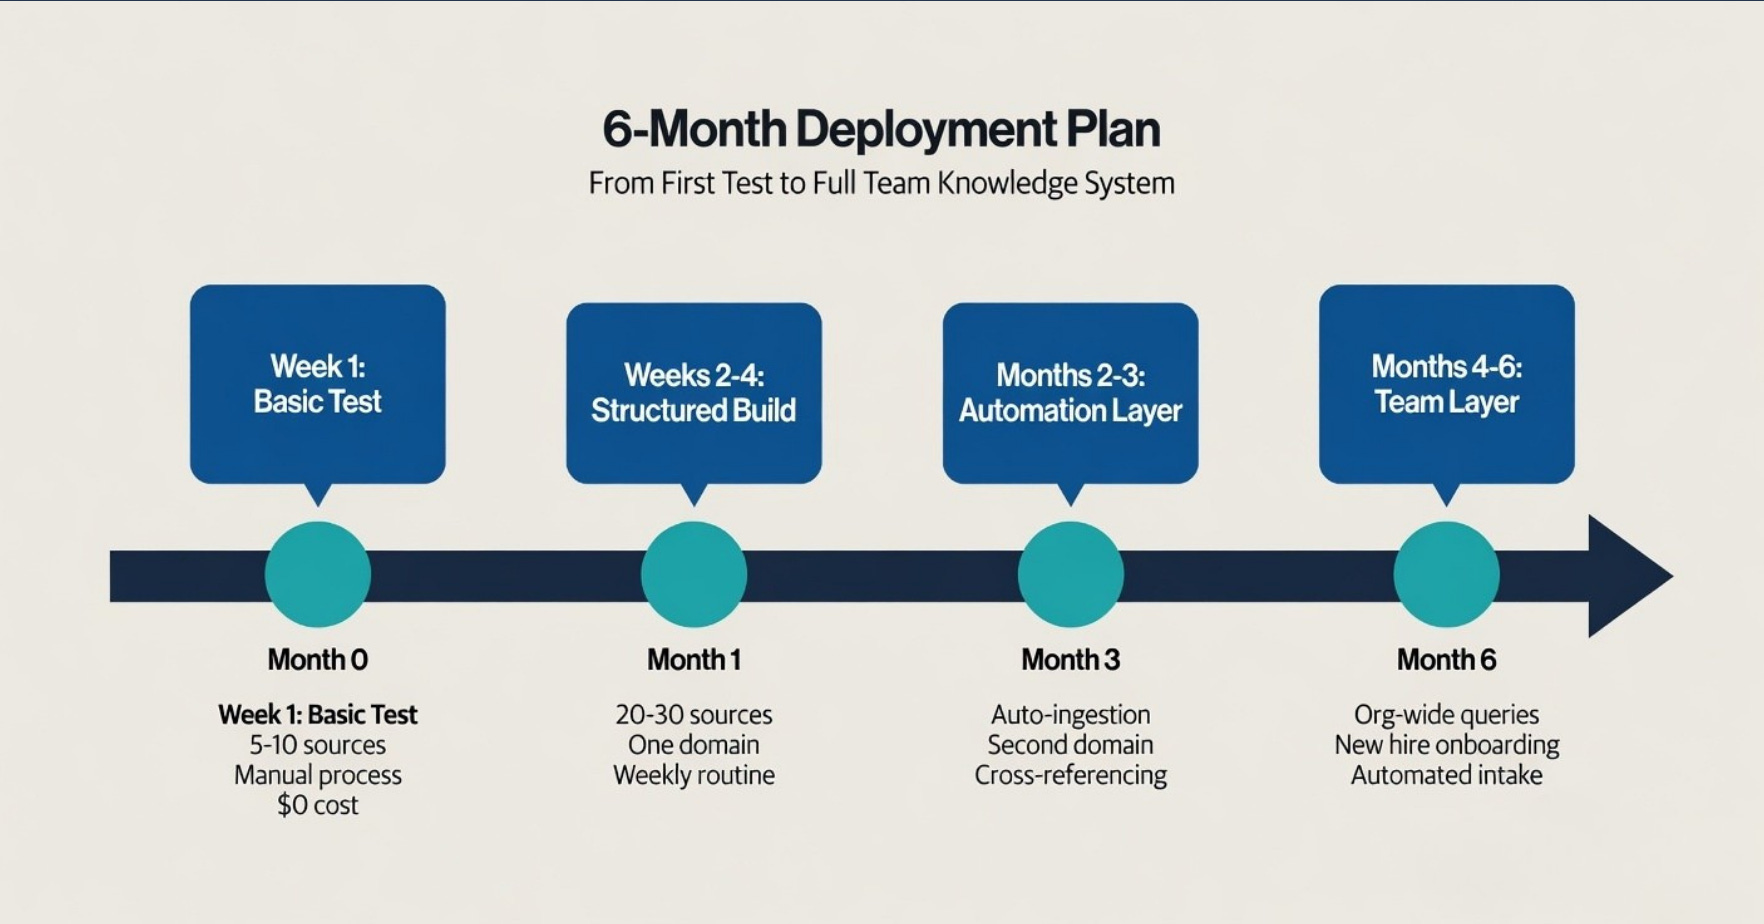
From First Test to Full Team Knowledge System: A 6-Month Plan
Week 1: Basic test
You have five to ten sources, a handful of wiki pages, and a real feel for how compiled knowledge differs from raw document search. Your schema is basic. Cross-references are manual.
One thing to validate: did the wiki surface a connection you hadn’t made yourself? If yes, the pattern works for your use case. If no, either your sources were too similar to each other, or your schema needs more page types.
Weeks 2 to 4: Structured build
Pick one knowledge domain. Competitive intelligence is usually the highest-ROI starting point because it’s where teams waste the most hours re-deriving the same answers.
Expand to 20 to 30 sources. Add the full schema with proper page types. Set up a simple weekly routine: every Friday, drop any new sources from the week into the raw folder and run an ingest pass.
You’ll start seeing patterns across sources. The wiki becomes your priority for any query.
Months 2 to 3: Automation layer
This is where Claude Code, or any tool with file access, earns its keep. Instead of manually copying content into ChatGPT, you set up automated ingestion. A new source arrives in the raw folder. The AI reads it, creates or updates wiki pages, and logs the operation. You review changes weekly instead of doing the work daily.
Add a second knowledge domain. Customer objections is the natural next step if you started with competitive intelligence, because objection responses almost always reference competitors.
The wiki starts compounding without you touching it daily. Two knowledge domains cross-reference each other. A pricing objection links to the competitor entity page, which links to the competitive pricing comparison, which links to the trend page tracking their pricing changes over time.
Months 4 to 6: Team layer
The wiki stops being personal and becomes organizational. Team members query it instead of asking each other. New hires onboard by reading wiki pages instead of knowledge-transfer meetings.
This is where most knowledge systems fail, and it’s not because the technology breaks. It’s because nobody feeds it.
The fix: make source intake automatic, not manual. Pipe Slack channels, call recording exports, and CRM deal notes directly into the raw folder using integrations or scheduled exports. The less your team has to remember to do, the more the wiki stays alive.
A personal wiki can be messy. A team wiki needs governance, but more than that, it needs automation that removes the human bottleneck from the intake side. Build it right at this stage and the payoff compounds indefinitely.
6 AI Knowledge Base Prompts: From Knowledge Audit to Weekly Maintenance
Copy-paste ready. These work with Claude, ChatGPT, Gemini, or any LLM. They go in order: strategy first, then planning, then implementation.
These prompts were tested against 20 scenarios across 15 industries, from pre-revenue startups to public companies, across 17 executive roles.
Prompt 1: The Knowledge Audit
Start here. This prompt finds where your organization keeps rebuilding the same answers from scratch.
You are a knowledge management consultant who specializes in diagnosing how organizations store, retrieve, and lose information across every industry and company size.

I run a [YOUR ROLE] at a [COMPANY SIZE] company in [INDUSTRY]. My team currently stores knowledge across these tools: [LIST YOUR TOOLS: Slack, Notion, Google Drive, CRM, ERP, email, WhatsApp, shared drives, spreadsheets, etc.]

Your job: identify the top 5 knowledge areas where my organization most likely re-derives answers from scratch instead of pulling from a maintained source.

Before you start the audit, classify my situation by thinking through these questions silently:

- Am I a solo operator or small team (under 5 people) where knowledge is concentrated in one or two heads? Or a larger team where knowledge is scattered across people and tools?
- Is this a pre-revenue or early-stage company where knowledge value is strategic positioning, not time savings?
- Does my industry involve regulated or compliance-sensitive knowledge (healthcare, fintech, legal, manufacturing quality) where the cost of not having the answer isn't wasted time but financial/legal/safety risk?
- Does knowledge in my organization live in digital shared tools, or is some of it in non-digital formats (verbal handoffs, WhatsApp groups, physical processes, in-person observations, ERP systems that aren't easily queryable)?

Use your classification to adapt how you run the audit:

1. What questions does my organization answer repeatedly? Think beyond the obvious. Include questions answered across departments, questions asked during crises or audits, and questions that only one person can answer today.

2. Where does the answer currently live? Consider: maintained shared docs, individual heads, email threads, chat messages, non-digital formats (verbal, observational), locked inside systems like ERPs or databases that people can't query naturally, or scattered across multiple locations with no single source.

3. Who needs this knowledge and how often? For larger teams, don't just count total headcount. Identify whether the knowledge is evenly distributed or concentrated in a few people. If 4 out of 18 salespeople hold all the tribal knowledge and the other 14 are flying blind, the actual need is 14 people, not 18. For solo operators or small teams, estimate how often the founder/operator personally needs to recall or reconstruct this information during client work, sales conversations, or decision-making.

4. What is the real cost of not having this knowledge maintained?
   - For operational knowledge: estimate weekly hours spent re-deriving
   - For compliance/regulatory knowledge: estimate the financial or legal risk of getting it wrong or being slow to find it
   - For strategic/competitive knowledge: estimate impact on deal win rates, positioning accuracy, or decision quality
   - For solo operators: estimate the opportunity cost of the founder's time spent reconstructing instead of doing higher-value work

For each knowledge area, give me:
- What the knowledge area is (be specific to my role and industry, not generic)
- Where the answer currently lives (or doesn't), including non-digital locations
- Who holds this knowledge today (distributed across team, concentrated in specific people, or exists only in systems)
- The cost metric that fits: hours/week wasted, risk exposure level, decision quality impact, or founder opportunity cost
- How often this knowledge changes (daily, weekly, quarterly, event-driven)

Don't give me generic categories like "internal communications" or "best practices." Every knowledge area should be specific enough that I can point to a real situation in my company and say "yes, that happens to us."

If my inputs leave anything ambiguous (especially around what tools are actually used day-to-day, whether knowledge is digital or not, or whether there are regulatory requirements), ask me clarifying questions before answering.
Prompt 2: The Priority Picker
Once you have the audit, this scores each knowledge area by type and tells you which one to build first. It’s not always the obvious choice.
You are a strategic operations advisor helping me decide where to invest effort first.

Based on the knowledge audit above, I need to pick one knowledge domain to build a compiled wiki for first. A compiled wiki is a structured, interlinked knowledge base that an AI maintains and updates, rather than raw document search.

Before scoring, classify each knowledge area by type. Different types need different scoring criteria:

Type A - Operational knowledge (team productivity): Score by weekly hours wasted re-deriving, number of people who'd query it, and how often the knowledge changes.

Type B - Revenue/growth knowledge (deals, pipeline, positioning): Score by direct impact on win rates, pipeline velocity, or churn. Also score on how many customer-facing team members would use it.

Type C - Risk/compliance knowledge (regulatory, legal, safety, quality): Score by cost of getting it wrong (fines, audit failures, legal exposure, safety incidents), how frequently regulations or requirements change, and how many compliance-dependent decisions happen per month.

Type D - Strategic/competitive knowledge (positioning, market intelligence): Score by how often strategic decisions depend on this information, how quickly the landscape changes, and how directly it shapes product or go-to-market direction.

Type E - Personal IP / founder knowledge (solo operators, small teams): Score by how often you need to recall this during client work or sales, how much of your competitive advantage depends on pattern recognition across past work, and how replaceable this knowledge is if you stopped being available.

For each knowledge area from the audit:
1. Assign a type (A through E)
2. Score it using the criteria that match its type (High / Medium / Low for each criterion)
3. Rate source readiness as a go/no-go gate, not just a factor: What percentage of raw sources already exist in a format an AI could read? If over 70% of the critical sources for a domain are locked in systems that can't be exported (ERP, POS, databases), or exist only as verbal/observational knowledge (WhatsApp groups, in-person handoffs), that domain is NOT buildable yet. Recommend the data consolidation work that needs to happen first, then pick the next-highest-priority domain where sources are actually accessible.

Then recommend the single highest-priority starting point. If my organization runs multiple distinct customer motions or business lines and no single domain covers all of them, recommend the domain that creates the most cross-domain learning (one that feeds into or informs the others).

For your recommendation, explain:
- Why this one wins
- What makes it the fastest to show results
- What source readiness work (if any) needs to happen before building can start
- Why the other areas should come later, not first

If any knowledge area scored as Type C (risk/compliance), flag it separately. Compliance knowledge may not be the highest-ROI starting point, but if the risk of not having it is severe enough, it might need to be prioritized on risk grounds regardless of efficiency scoring.

If you end up recommending a Type C (risk/compliance) domain over the highest-efficiency domain, explain why the risk justification overrides the efficiency ranking. Don't present two conflicting recommendations. Pick one, defend it, and explain the tradeoff.
Prompt 3: The Schema Builder
This designs the full schema for your wiki: page types, folder structure, cross-referencing rules, naming conventions, all adapted to your industry and source types. The output is something an AI can follow without asking you what to do every step.
You are an information architect designing a structured knowledge system. You've built these for SaaS companies, consulting firms, healthcare organizations, manufacturing operations, franchise businesses, and regulated industries. You adapt the schema to the domain, not the other way around.

I want to build a compiled knowledge wiki for [DOMAIN: competitive intelligence / customer objections / deal intelligence / product knowledge / regulatory compliance / supplier intelligence / clinical evidence / operational playbooks / etc.]. In this system, an AI reads raw source documents and creates structured, interlinked wiki pages that it maintains over time, rather than searching raw docs from scratch each time.

My industry: [INDUSTRY]
My raw sources will include: [LIST YOUR SOURCES: call transcripts, competitor websites, G2 reviews, internal docs, ERP exports, regulatory filings, audit reports, POS data, WhatsApp messages, data exports, spreadsheets, etc.]

Before designing the schema, classify my situation:

- Source types: Are my sources mostly narrative text (transcripts, articles, emails)? Structured data (CSV exports, database tables, ERP data, POS logs)? A mix? This determines how ingestion rules should work.
- Domain type: Is this standard business knowledge (competitive intel, deal patterns, playbooks)? Regulated knowledge (compliance, clinical, legal) that needs source authority tracking and version history? Operational knowledge (SOPs, processes, location-specific variants) that needs variant tracking?
- Scale: Will this wiki be used by one person, a small team, or a large organization? This determines governance rules.

Design a complete wiki schema. Deliver these sections:

1. Folder structure: How to organize both raw sources (by type, including a separate path for structured data sources) and wiki pages (by page type). Use clear folder names.

2. Page types: Generate page types appropriate for MY domain and industry, not just the defaults. Start with the universal types (entity, concept, source summary, pattern, synthesis) and then add domain-specific types.
   - For regulated industries: add regulatory summary pages, interpretation history pages, and compliance status pages with fields for regulatory authority, effective date, and jurisdiction.
   - For product/engineering: add decision record pages with fields for decision criteria, alternatives considered, tradeoffs, and rejection rationale.
   - For consulting/agencies: add framework library pages and engagement retrospective pages.
   - For operations/franchises: add SOP pages with variant tracking. Variants can be location-based (different processes per site), time-based (seasonal playbooks), customer-segment-based (different approaches per segment), or product-line-based. The variant structure should support a baseline version plus any number of conditional overrides with clear labels for when each override applies.
   - For data-heavy domains: add metric summary pages and cohort analysis pages.
   For each page type: what it captures, when to create one, and a sample frontmatter template (YAML metadata). If my domain requires compliance, regulatory, or authority metadata, include those fields in the frontmatter.

3. Cross-referencing rules: Which page types should link to which. How to handle references to pages that don't exist yet. If my sources come from different systems with different levels of detail (e.g., CRM deal notes vs. call transcripts vs. product usage data), specify how pages from different source granularities should reference each other.

4. Quality rules: When the AI should update an existing page vs. create a new one. When to flag a genuine contradiction (two sources from the same period claiming different things) vs. a temporal update (information changed over time) vs. a context-dependent variation (different answers for different segments, locations, or use cases). What minimum information a page needs before it counts as complete.

5. Naming conventions: How to name files so they stay organized as the wiki grows past 50 pages. Include conventions for versioned content (regulations that change, pricing that updates, SOP revisions).

6. Structured data handling: If my sources include data exports, spreadsheets, or system extracts, specify how to ingest them. Should the AI create summary pages from tabular data? Should it extract key metrics into metric pages? How should it handle rows with many fields without creating a page per row?

Keep the schema tight enough that I can set it up in under 2 hours but detailed enough that an AI can follow it without asking me what to do every step.

Don't over-engineer. Start with the minimum viable schema that I can expand later. But don't under-engineer either. If my domain needs compliance, authority, or variant tracking, include those from the start because retrofitting them is harder than building them in.
Prompt 4: The Source Prioritizer
You probably have more sources than you think, and most of them are the wrong ones to start with. This ranks which documents to feed in first and flags which ones are locked in systems you can’t export yet.
You are an information architect helping me decide which documents to feed into my knowledge wiki first. The goal is to build the most useful initial wiki with the fewest sources.

My wiki domain: [DOMAIN]
My industry: [INDUSTRY]
My wiki schema: [PASTE OR SUMMARIZE YOUR SCHEMA FROM PROMPT 3]

Here are the raw sources I have access to:
[LIST EVERYTHING: tools, document types, locations, approximate quantity of each. Include digital sources (docs, spreadsheets, exports), system-locked sources (ERP, CRM, POS data), and non-digital sources (verbal knowledge, WhatsApp messages, in-person observations) if relevant.]

Before ranking, classify each source type:

- Narrative sources (transcripts, articles, emails, meeting notes): Rich in context but require extraction.
- Structured data sources (CSV exports, database tables, spreadsheet reports, ERP/POS data): Dense in facts and metrics but lack narrative context.
- Authoritative sources (regulatory filings, official guidance, audited reports, board-approved docs): These carry more weight than informal sources regardless of other criteria. In regulated industries, an official agency document always outranks an internal interpretation memo.
- Informal/conversational sources (Slack threads, WhatsApp messages, verbal handoffs): Context-rich but unreliable as sole sources. Best used to supplement authoritative sources.

Rank sources using four criteria:

1. Information density: How much unique, actionable knowledge does this source contain that doesn't exist in other sources? Note: density means learning per source, not text volume. A 20-person engagement retrospective may be denser than 50 individual email threads.

2. Cross-reference potential: Will this source create connections between multiple wiki pages (entities, concepts, patterns)? Sources that mention multiple entities or span multiple topics rank higher.

3. Source authority: How reliable and definitive is this source type? Official docs, audited reports, and system-of-record data rank above informal messages and anecdotal notes. In regulated domains, always rank regulatory/legal sources first.

4. Currency: How current is this information and how much does currency matter for this domain? For operational knowledge, recent data beats old data. For regulatory knowledge, the most authoritative version matters more than the most recent opinion. For historical decisions (architecture records, past engagement learnings), the source is valuable regardless of age.

Also check for dependency chains: Are any sources interdependent? (Example: Architecture decision records that reference earlier ADRs. Compliance interpretations that depend on specific regulatory statutes being ingested first.) If so, note the dependency order and ensure foundational sources (the ones others depend on) are included in the top 10-15 even if they individually rank lower on the other criteria. A lower-density source that 5 other sources reference is more important to ingest first than a high-density source that stands alone.

From your ranking, pick the top 10 to 15 individual documents I should ingest first. For each one, tell me:
- What it is and what source type it is (narrative, structured, authoritative, informal)
- Why it ranked high
- Which wiki page types it will likely generate
- Whether it depends on another source being ingested first

Flag source gaps: If a page type in my schema won't have sources feeding it from this initial batch, tell me exactly what kind of document I need to find or create. If my domain requires coverage of multiple variants (states, locations, customer segments, product lines), flag whether my top 15 sources cover enough variants or leave blind spots.

Flag source readiness issues: If any high-value sources are locked in systems that aren't easily exportable (ERP, POS, databases), or exist only as non-digital knowledge (verbal, observational), flag those separately and suggest how to extract or capture them before ingestion.
Prompt 5: The First Ingest
This processes your first source document into structured wiki pages with cross-references, confidence metadata, and an operations log. It handles narrative text, structured data, regulatory documents, and incident reports differently, because they all need different ingestion approaches.
You are a knowledge base curator. Your job is to read a raw source and create structured wiki pages following a defined schema. Precision and cross-referencing matter more than speed.

Here is my wiki schema:

[PASTE YOUR SCHEMA FROM PROMPT 3]

Here is the raw source to ingest:

[PASTE THE DOCUMENT OR DATA]

Read the full source before creating any pages. First, classify the source type, because different types need different ingestion approaches:

**If the source is narrative text** (transcript, article, email thread, meeting notes, blog post, report):
- Identify every entity (person, company, product, tool), concept, and pattern mentioned.
- Create wiki pages following the correct page type and frontmatter from the schema.

**If the source is structured data** (CSV export, spreadsheet, database table, ERP extract, POS data):
- Do NOT create one wiki page per row. Instead, extract the key dimensions (what are the column headers telling you?) and the key findings (what patterns, outliers, or summary metrics emerge from this data?).
- Create metric summary pages or pattern pages that describe what the data shows, with references to specific data points as evidence.
- Create entity pages only for the major entities represented in the data (top suppliers, top products, key customer segments), not for every row.

**If the source is behavioral/event data** (analytics exports, user activity logs, conversion funnels):
- Identify the key behavioral patterns, not individual events. What user actions correlate with outcomes? What sequences matter?
- Create pattern pages for behavioral findings and metric pages for key numbers.
- Link behavioral patterns to any entity pages they inform (products, features, customer segments).

**If the source is regulatory/compliance/legal** (statutes, agency guidance, audit reports, legal memos):
- Identify regulatory entities (agencies, statutes, jurisdictions) and create entity pages with fields for authority level, effective date, and jurisdiction.
- Track version history: if this regulation replaced or amended an earlier version, note that in the frontmatter.
- Set confidence based on source authority, not just source count. An official regulatory filing is high confidence from a single source. An internal interpretation memo is lower confidence even if it's detailed.

**If the source is incident/operational** (postmortems, incident logs, runbooks, outage reports):
- Identify system components, failure modes, causal chains, and timeline sequences, not just people and companies.
- Create entity pages for system components involved and pattern pages for failure modes.
- Preserve temporal sequence (what happened first, what triggered what) in the source summary page.

After classification, follow this process for all source types:

1. Create wiki pages following the correct page types and frontmatter from the schema. Apply domain-specific metadata fields if your schema includes them (regulatory authority, confidence level, version, jurisdiction, etc.).

2. Add [[wikilinks]] to connect pages. If a linked page doesn't exist yet, create a stub ONLY if that entity or concept is likely to appear in future sources. For one-off mentions that probably won't recur, note the reference in the current page without creating a stub. This prevents stub explosion in information-dense sources.

3. Create a source summary page with: key takeaways, action items (if any), entities and concepts identified, pages created, and links to every wiki page generated.

4. Set confidence levels based on source authority. Use two frontmatter fields: `confidence` (high/medium/low) for how reliable the information is, and `authority_source` (the specific source type) so downstream maintenance passes can compare authority levels when conflicts arise.
   - Official records, audited data, regulatory filings, system-of-record exports: confidence: high, authority_source: official
   - Meeting notes, call transcripts, internal memos from known experts: confidence: medium, authority_source: internal-expert
   - Informal messages, anecdotal reports, single-person observations, unverified claims: confidence: low, authority_source: informal
   - If a claim from a lower-authority source contradicts a higher-authority source, flag the contradiction explicitly and note the authority mismatch.

5. Produce an index update (page name, page type, status, confidence) and log this ingest operation with date, source name, source type, pages created, stubs created, and any contradictions or flags.

Quality check before delivering: Does every page have proper frontmatter including confidence? Are cross-references bidirectional? Are stubs limited to entities likely to recur? Is the source summary complete? For structured data sources, did you create summary/pattern pages instead of per-row pages?
Prompt 6: The Weekly Maintenance Pass
This keeps your wiki from going stale. It integrates new sources, separates actual contradictions from information that just changed over time, flags synthesis opportunities when three or more independent sources point at the same thing, and logs every operation so you know what changed and why.
You are a knowledge base curator running a maintenance pass. Your job is to integrate new sources into an existing wiki without breaking cross-references, creating duplicates, or confusing temporal updates with actual contradictions.

Here are the new raw sources from this period:

[PASTE OR DESCRIBE NEW SOURCES]

Here is the current state of my wiki (existing pages):

[PASTE YOUR INDEX OR PAGE LIST]

For each new source, follow this process:

1. Read fully and classify the source type (narrative, structured data, regulatory, incident, behavioral) before making any changes. Use the same source type classifications from the First Ingest prompt.

2. Map to existing pages. Which existing wiki pages contain information that this source adds to, updates, or contradicts?

3. Before making any changes, classify each piece of new information into one of three categories:

   **Temporal update:** The real-world fact changed over time. A supplier's price went from $15 to $18. A conversion rate improved from 9% to 12% in a new quarter. A competitor released a new feature. A regulation was amended.
   Action: Update the current-state fields on the page (current_price, latest_version, current_status). Move the old value to a changelog or history section with the date it was valid. Do NOT flag as contradiction.

   **Context-dependent variation:** The information differs because it applies to a different context. A sales playbook for manufacturers recommends different messaging than the playbook for distributors. An SOP varies by location. Messaging that works for one customer segment doesn't work for another.
   Action: Add the variation as a conditional section on the page (e.g., "For manufacturers: ..." / "For distributors: ...") or create a linked variant page if the differences are substantial. Do NOT flag as contradiction.

   **Actual contradiction:** Two sources from the same time period, about the same context, claim different things. One call transcript says the prospect's budget is $50K, another says $30K. One team member documented a process one way, another documented it differently.
   Action: Flag as a genuine contradiction. Add both versions with their sources. Hold for human resolution.

4. Apply the classified changes:
   - For temporal updates: overwrite current-state fields, preserve history with dates.
   - For context-dependent variations: add conditional sections or variant pages.
   - For contradictions: flag and hold.
   - For genuinely new information that adds detail to an existing page: append. Add the new source as a reference. Update the "last updated" date.
   - For high-frequency data sources (weekly analytics, daily call transcripts, regular data exports): maintain a rolling window. Keep detailed data from the last 8 weeks. Summarize older data into trend pages rather than appending indefinitely.

5. Create new pages only if the source covers entities, concepts, or patterns not yet in the wiki. Follow the schema for page type, frontmatter, and domain-specific metadata. Apply the same stub rules from the First Ingest: only create stubs for entities likely to recur.

6. Update cross-references. New pages should link to relevant existing pages, and existing pages should link back.

7. Check for synthesis opportunities. If this maintenance pass touched multiple related pages AND the pattern spans 3 or more independent sources AND the pattern is actionable for the business, note it in a "Synthesis opportunities" section of the log. Example: two competitors both made pricing changes in the same direction, or the same objection appeared in calls with 3 different customer segments. Don't flag loose correlations. Only flag patterns a human should consider turning into a synthesis page.

8. Check for causal or precedent chains. Two specific situations to watch for:
   - Incident/operational: If the root cause of a new incident matches or resembles the root cause of a previous incident (even if they occurred in different systems or components), flag the causal connection. Look for shared failure modes, shared infrastructure dependencies, or shared environmental conditions, not just surface-level similarity.
   - Regulatory/compliance: If a regulatory change in one jurisdiction is likely to affect interpretations in other jurisdictions, flag it only if those jurisdictions have harmonization clauses, explicitly reference each other's laws, or share a common regulatory framework. Don't flag every state change as relevant to every other state.

9. Log the operation: Date, sources ingested (with source type), pages created, pages updated, temporal updates applied, context variations added, contradictions flagged, synthesis opportunities noted, precedent/causal chain flags.

Before delivering, show me a change summary grouped as:
- Pages to create (with page type)
- Pages to update (grouped by: temporal updates, new detail appended, context variations added)
- Contradictions found (with both versions and sources)
- Synthesis opportunities (cross-page patterns worth investigating)
- Precedent/causal flags (if any)

Wait for my confirmation before finalizing.
These six prompts are enough to build the whole thing from scratch. If you’d rather not start from scratch, the full system is available as a free download: pre-built schemas, folder structure, automation scripts, and maintenance workflows. Drop it into Claude Code or Claude Cowork and you’re running in minutes instead of hours.
Grab it free on Gumroad: GTM Knowledge System Kit - Self-Updating Wiki Builder
For industry-specific use cases, team-specific wiki design, and stage-appropriate buildout plans, the Gumroad package goes deeper than what fits in a newsletter.
Frequently Asked Questions
What is a compiled knowledge base?
It’s a structured wiki that an AI builds and maintains from your raw documents: call transcripts, meeting notes, competitor research, whatever you have scattered across tools. Instead of searching those raw files every time, the AI reads each source once, creates interlinked wiki pages, and updates them when new information arrives.
How is this different from RAG or NotebookLM?
RAG (retrieval-augmented generation) and tools like NotebookLM search your raw documents every time you ask a question. They start from scratch. Ask the same question twice and you might get different answers because they pulled from a different set of documents.
A compiled knowledge base synthesizes once and keeps the result. When you ask a question, the AI queries pre-compiled pages with cross-references and changelogs, not a pile of unorganized files. The answers are faster, more connected, and consistent.
What tools do I need?
At minimum: a markdown editor (Obsidian or Logseq work well, both free) and an LLM with file access (Claude Code, ChatGPT, or a local model like Ollama). The architecture is tool-agnostic. You can test it for free in 90 minutes using ChatGPT’s free tier and any markdown editor.
How long does it take to set up?
A basic test with five to ten source documents takes about 90 minutes. A structured build for one knowledge domain, like competitive intelligence, takes two to four weeks. Full team deployment with automation is a four to six month project. The architecture scales. You don’t have to do it all at once.
Does this work for non-SaaS companies?
Yes. The prompts here were tested across 20 industries: manufacturing, healthcare, consulting, franchise operations, regulated industries, solo operators. The architecture is identical regardless of industry. What changes is the page types and schema. The prompts handle that adaptation automatically based on what you tell them about your domain.
What did Karpathy actually propose?
Karpathy, founding member of OpenAI and former head of AI at Tesla, published a concept in April 2026: instead of searching raw documents with every query, have an LLM compile a structured wiki from those documents. His system uses three layers: raw sources the AI reads but never modifies, wiki pages the AI creates and maintains, and a schema that defines how to compile. His personal version grew to roughly 100 articles and 400,000 words, none of which he wrote directly. He fed sources and let the system build itself.
Can I use this with Notion, Confluence, or Google Drive?
Yes. Those tools become your source material, not the wiki itself. Export documents from them into your raw sources folder. The AI reads them and builds wiki pages from what it finds. The wiki lives as markdown files you can store locally or in any tool that supports markdown. You don’t have to give up the tools your team already uses. They just move down a layer.
Three Ways to Start Building
You’ve read the architecture, the examples, and the prompts. Here’s how to actually move on it.
Path 1: Try the prompts yourself
Everything you need is in this newsletter. Copy Prompt 1, run the knowledge audit, and work through the sequence. You’ll have a working test wiki in 90 minutes using free tools. This path is for people who like building from scratch and want full control over every decision.
Path 2: Download the full system (free on Gumroad)
I packaged the entire compiled knowledge base system into a ready-to-run download. Pre-built schemas for competitive intelligence, customer objections, and deal intelligence. Folder structure already set up. Automation scripts for source ingestion and weekly maintenance. Prompt library that goes deeper than what fits in a newsletter.
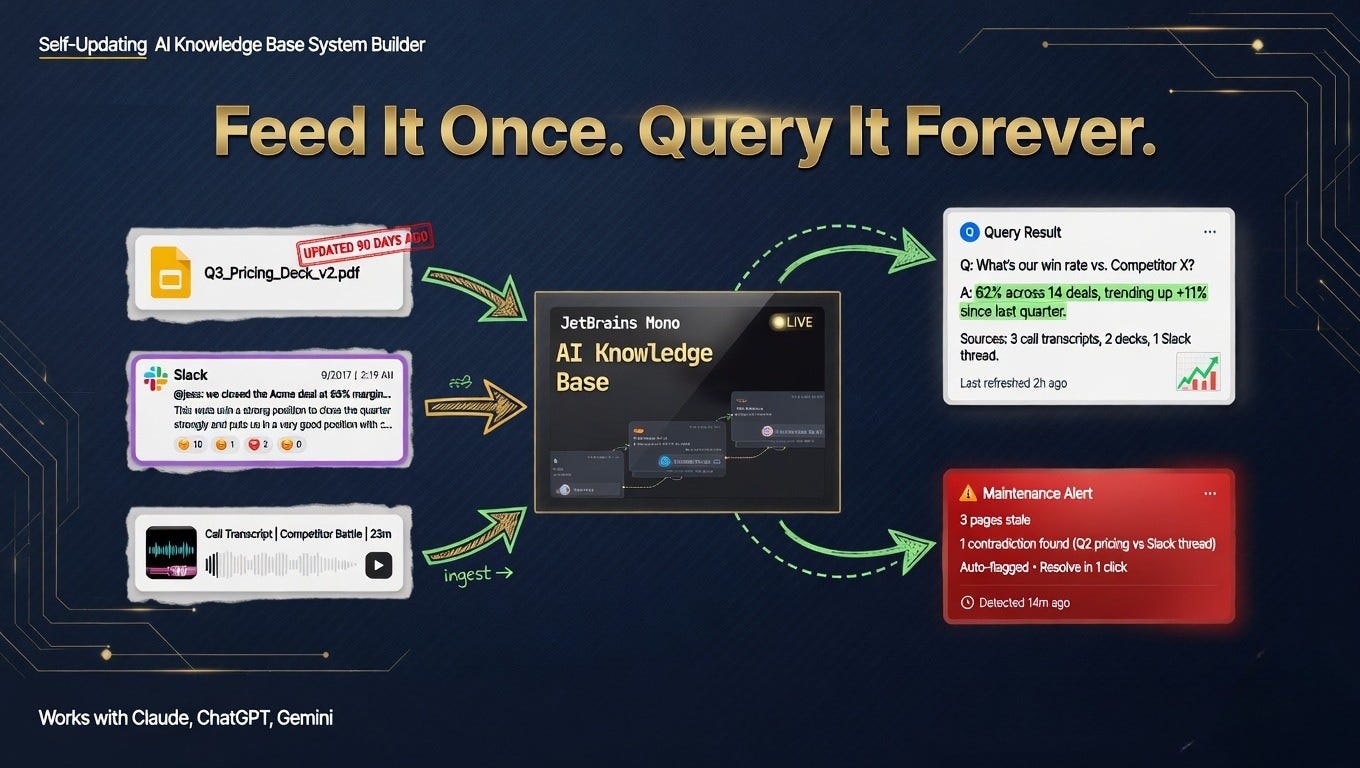
Drop it into Claude Code or Claude Cowork and you’re running in minutes. No manual setup. No figuring out folder structures or schema syntax. One click and you’re building wiki pages from your first source document.
[GET THE FULL WIKI SYSTEM ON GUMROAD]
Path 3: Get it built for your team
If you read this and thought “I get the concept but I need someone to map this to my specific situation,” I run paid implementation sessions where we build your knowledge architecture together.
We’ll audit where your team’s knowledge is leaking, design the schema for your domain, pick your first 10 source documents, and get the wiki running before the session ends. You walk away with a working system, not a plan to build one later.
This is for teams that want it done right the first time and don’t want to spend four weeks figuring out page types and cross-referencing rules on their own.
Every quarter, your team rebuilds knowledge that already existed somewhere. That’s not a process problem. That’s a compounding loss. The system to fix it is in this newsletter. The only question is whether you’ll build it or keep paying the tax.
Loved this?
And subscribe to “Prompts Daily Newsletter” as well…
If you’re not a subscriber, here’s what you missed earlier:
The CXO Newsletter Playbook: Why 95% Fail (And the 5-Prompt Strategy System)- Part 1 of 2
Your Head of Growth Toolkit (with Context, Prompts and Agents)
Analyze your Content for Trust and Revenue Goals with Claude (using Content Trust System)
Build an ICP so specific your message gets reply - The Pressure Profile ICP System (with Prompts)
I get 3x more inbound from comments than posts - My entire prompt system
The AI Partner Stack: 8 Roles as My Advisory Board (Part 2 of 2)
How You Should Actually Plan 2026: [Implementation Guide with Prompts]
Find trends before others: Frameworks, Techniques, Sources and Prompts
The Market Entry Timing Equation: When Being Early Wins and When It Kills You
The Viral LinkedIn GTM Playbook: Frameworks That Drove Engagement and Leads
Subscribe to get access to the latest marketing, strategy and go-to-market techniques . Follow me on Linkedin and Twitter.
Thanks for reading StartupGTM’s Substack! Subscribe for free to receive new posts and support my work.
WOW! I read every word that you wrote; my head is spinning. I was getting ready to deploy Claude CoWork, but now I think I need to build a Wiki.